Your clients should not have to take your word for it.
Evidova evaluates every conversation your voice and chat AI agents have, and monitors quality live. You get the evidence. Your client gets a report you did not write.
One agent, no contract. You keep the report either way.
Never answered the deposit question
What's the security deposit on the 2BHK?
You can find all pricing details in our brochure. The link is below.
 Retell
 Vapi
 Bolna
 ElevenLabs
 WhatsApp
 Gupshup
 WATI
 Twilio
 Intercom
 Crisp
 Messenger
 ZendeskCustom stack
One figure shows where conversations end, and why.
Total volume enters as a single ribbon and narrows turn by turn as users give up. Red streams need a product fix, amber could have been saved, green reached resolution. Click any stream and you land on the conversation’s verdict and the exact turns behind it, filtered to the client and agent it came from.
Where and why 8,642 conversations left.
A number nobody can check
is just an opinion.
So every score opens onto the conversation that produced it. Three things, on every conversation, every time.
- The verdict
- Pass, fail or partial, against the rule you wrote.
- The evidence
- The exact turn it came from, quoted.
- The agreement
- Which judges concurred, and how often they match a human reviewer.
Proof you can forward to a client.
Four slices of the console. Every figure opens its spread of scores, its per-area breakdown, and the quotes behind the score. You check the method, not just the number.
Agreement with humans, measured and shown
Three AI judges, each from a different company, score every failure separately. When they disagree, a fourth judge decides instead of splitting the difference. We then compare verdicts with human reviewers and show you the match rate, for every client and every score.
How often independent judges reach the same verdict, with the agreement you’d get from luck alone taken out. 1.00 is perfect agreement.
Checked against examples a person scored by hand. Flag accuracy: when we flag a failure, how often it’s real. Catch rate: of the real failures, how many we catch.
- Task successAgreement 0.92 · 180 scored
- ComplianceAgreement 0.90 · 140 scored
- FaithfulnessAgreement 0.87 · 160 scored
- ToneAgreement 0.81 · 160 scored
Every conversation someone gives up on gets a reason
- Out-of-scope requestMedium impact1.21,173
- Repeated question, gave upHigh impact2.8988
- Slow reply, user leftHigh impact4.1961
- No response after promptMedium impact0.4879
- Policy: steering languageHigh impact0.9693
- Pricing confusionLow impact1.6388
Stable taxonomy · 5,082 gave up · Last 24h
Watch conversations as they land
One standard across phone, WhatsApp, and web
- WhatsApp5,120 · Score 85
- Call2,410 · Score 82
- Chat1,112 · Score 87
A call and a chat become comparable numbers.
The grader has no stake in the grade
A platform grading its own calls is marking its own homework. Evidova sits outside the stack that produced the conversation. It has nothing to defend when a score comes back low.
Point a webhook at us, post events from a stack of your own, or hand us a year of history. The rules are yours. Every number opens onto the transcript behind it, and the conversations we screened out are named too, with the reason.
Works with whatever you run.
Voice platforms, WhatsApp providers, support desks, or a custom stack. Evidova reads from the outside. Nothing to rip out, nothing to migrate.
- Webhookzero-code
- Point your platform's event stream at Evidova. No code.
- Events APIany stack
- Post conversations from a stack of your own, one event per turn.
- Bulk importhistorical
- Backfill months of history in one pass; it gets scored retroactively.
The same rules score every channel, so results are comparable across all of them.
From raw traffic to a proven fix.
- 01
Connect
Point your voice or chat platform's webhooks at Evidova, post events from a stack of your own, or bulk-import the history you already have. Most teams connect without writing code.
RetellVapiWhatsAppElevenLabsWATITwiliowebhookevents APIbulk importor your ownCalls and chats land raw (audio, transcript, every action the agent took) and become one reviewable record.
- 02
Score every conversation
Instant checks on reply speed, stalls, and giving up cover 100% of traffic within seconds. AI judges review a live sample as it happens, and every conversation gets the full review overnight.
Sample dataVerdictFlag84/ 100High confidenceFully reviewed · 3 judgesAnswers74Policy90Reply speed88Three judges from different companies; when they disagree, a fourth judge decides; agreement with human reviewers published.
- 03
Learn why users leave
Each conversation where someone gave up is tagged with a reason from a stable taxonomy. The reasons are ranked by how much volume and value it costs.
Sample dataTop reasons5,502 gave up · 7d#1Out-of-scope request−1,270#2Repeated question, gave up−1,070#3No response after prompt−952A fixed set of reasons that stays comparable week to week, ranked by damage done. Every reason opens real conversations.
- 04
Prove the fix worked
Ship a change and review it again against the same rules. The before-and-after is measured, and you can forward it to the client it affects.
Sample dataRegression checkImproving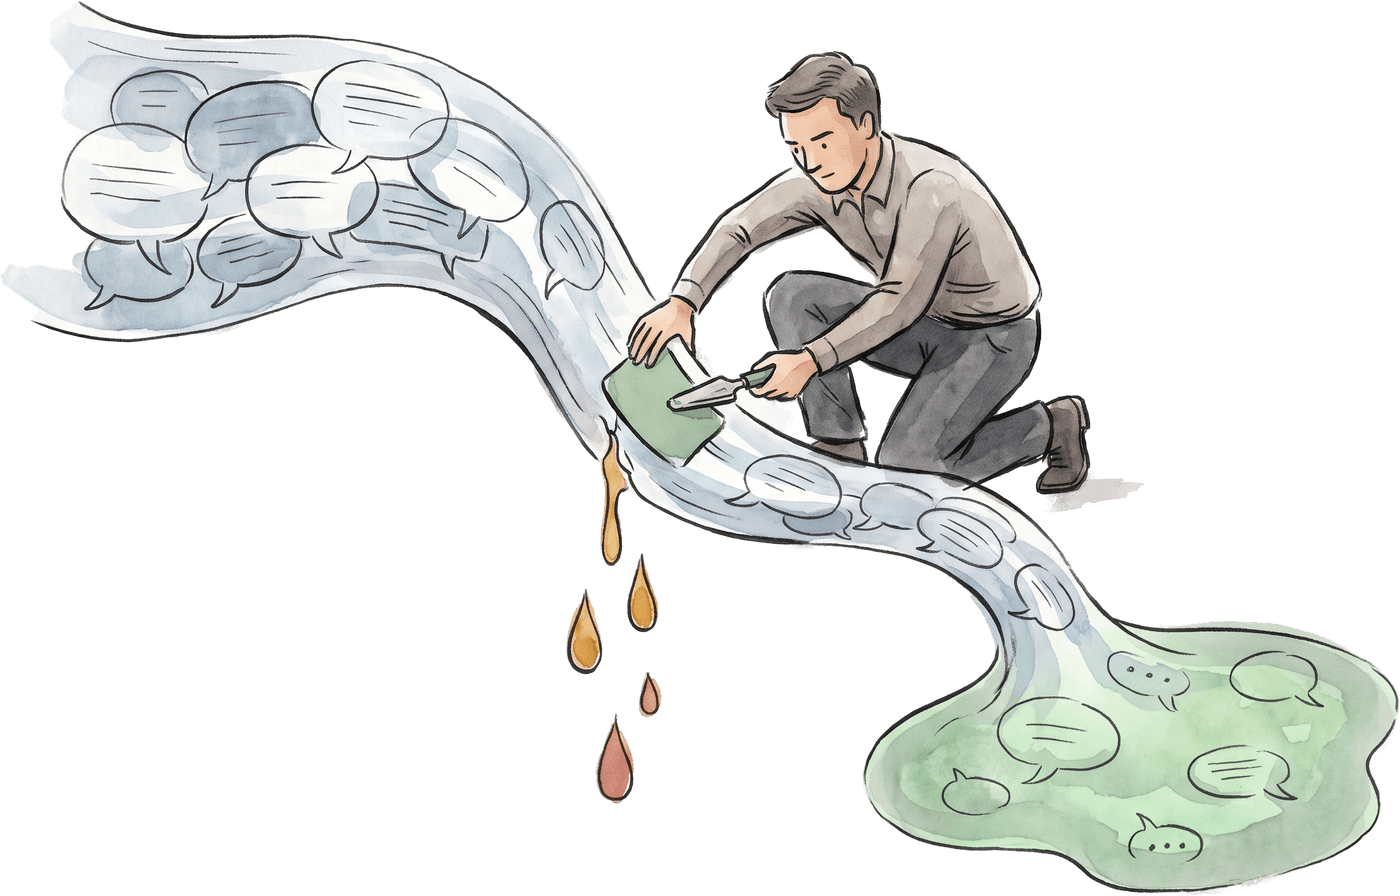 Repeated question, gave up · share of total−24%
Reviewed again with the same checks and the same reasons. The before-and-after is measured, not eyeballed.
The questions that come up first.
Short answers, and honest ones. Ask us the rest on the call.
What does Evidova actually tell us?
Which conversations went wrong, why, and which fix moves the number most. Every conversation is scored against your own rules, every failure is grouped by root cause, and every claim opens onto the transcript underneath it. You stop arguing about whether quality is slipping and start reading where.
How fast do we see something useful?
Day one. Point a webhook at us or import your history, and the deterministic checks score all of it in seconds. Most teams find where callers are giving up before they have had a meeting about it.
Do we have to change our AI agent stack?
No. Evidova reads what your stack already produces. Webhooks from Retell, Vapi, Bolna, ElevenLabs, WhatsApp providers and support desks. Your own events when a stack is custom, or a bulk import of history. Nothing to rip out.
How do we know an agent quality score is right?
Because you can check it. Several AI judges from different companies score each conversation on their own, and a fourth settles a disagreement. We measure them against human reviewers and publish how often they agree. A score carries its own confidence instead of asking for your trust.
Who decides what counts as a failure?
You do. Start from our rules for your industry or bring your own, then edit them as plain sentences. Every rule is versioned, so when a score moves you can tell whether the agent changed or the rule did.
Does it monitor voice agents as well as chat agents?
Both, under the same rules. Calls are transcribed and timed, so a silence that killed a call is as visible as a wrong answer in a chat. The two channels are finally comparable.
Does it work in our languages?
Yes, including code-switched traffic. English, Hindi, Tamil, Telugu and Hinglish today, on voice and chat alike, scored by the same rules on every channel.
What happens when quality drops overnight?
You get told. You set the limit, Evidova watches it, and the alert arrives by email or WhatsApp with the conversations that triggered it attached. Monday brings a digest of what fired and what the team closed, so the people who never open a dashboard still know.
Can our clients see their own numbers?
Yes, and only their own. Dashboards, baselines and the weekly report are scoped per client. Give one client read-only access to their slice, or just send the report. Nothing leaks across accounts.
Audit one agent. Then decide.
Bring one agent. We connect a webhook or import history, score every conversation, and walk you through where users leave and why, on a call. If the audit tells you nothing new, that’s worth knowing too.
Early and invite-only. The demo above runs on synthetic data. Yours runs on your own conversations.